

What is PerplexityBot?
Definition
PerplexityBot is Perplexity's crawler for surfacing and linking websites in Perplexity's search results. According to Perplexity, it is not used to crawl content for AI foundation models. A separate user agent, Perplexity-User, visits pages on demand when a user asks a question, and because the user requested the fetch, it generally ignores robots.txt rules.
Also known as: Perplexity crawler, Perplexity bot, Perplexity user agent
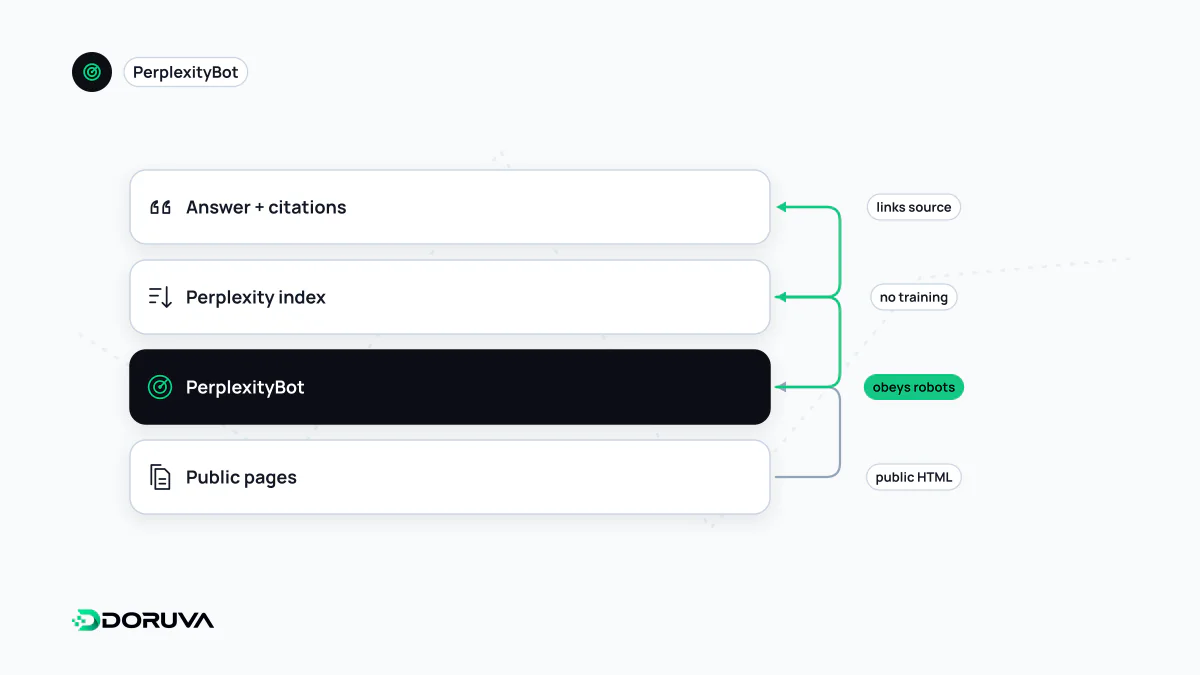
Two separate user agents
Perplexity's bot documentation defines two user agents that behave differently with respect to robots.txt:
| PerplexityBot | Perplexity-User | |
|---|---|---|
| Purpose | Surfacing and linking websites in Perplexity search results | Visiting a page to help answer a user's question |
| Model training | Not used to crawl content for AI foundation models | No training purpose described; supports user actions |
| robots.txt | Respects it | Generally ignores it, since the user requested the fetch |
| IP list | https://www.perplexity.com/perplexitybot.json | https://www.perplexity.com/perplexity-user.json |
Unlike OpenAI and Anthropic, Perplexity does not list a separate training crawler. PerplexityBot's role is closest to OpenAI's OAI-SearchBot: feeding an AI search product.
User-agent strings
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)

Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)
To confirm that requests using these names really come from Perplexity, compare their IP addresses with the ranges in the JSON lists above.
What robots.txt can and cannot do
To block PerplexityBot:
User-agent: PerplexityBot
Disallow: /
Read the effect carefully. Because the bot exists to surface sites in search results, blocking it affects your chances of appearing as a source in Perplexity search, not model training. Perplexity-User is not bound by this rule: when someone asks about your page directly, it may still be fetched. Stopping user-triggered access for certain would take measures beyond robots.txt, at the server or firewall level, and that would also reduce your visibility in Perplexity.
Common misunderstandings
- "Blocking PerplexityBot keeps my content out of model training." Perplexity already states that PerplexityBot does not crawl for foundation model training. A block made for that reason mainly affects search visibility.
- "Perplexity-User shows up in my logs, so my robots.txt is broken." Perplexity documents that Perplexity-User acts on user requests and generally ignores robots.txt; this is not a configuration error.
- "
Disallow: /underUser-agent: *stops everyone." It only means something to bots that follow robots.txt.
The visibility angle
Perplexity shows its sources as numbered links in its answers, so pages the bot can reach and that answer questions clearly and directly are candidates for an AI citation. Access is a prerequisite, not a guarantee; which sources are chosen is up to Perplexity's own systems.
For the general logic of writing these rules, see robots.txt.