

What is Perplexity-User?
Definition
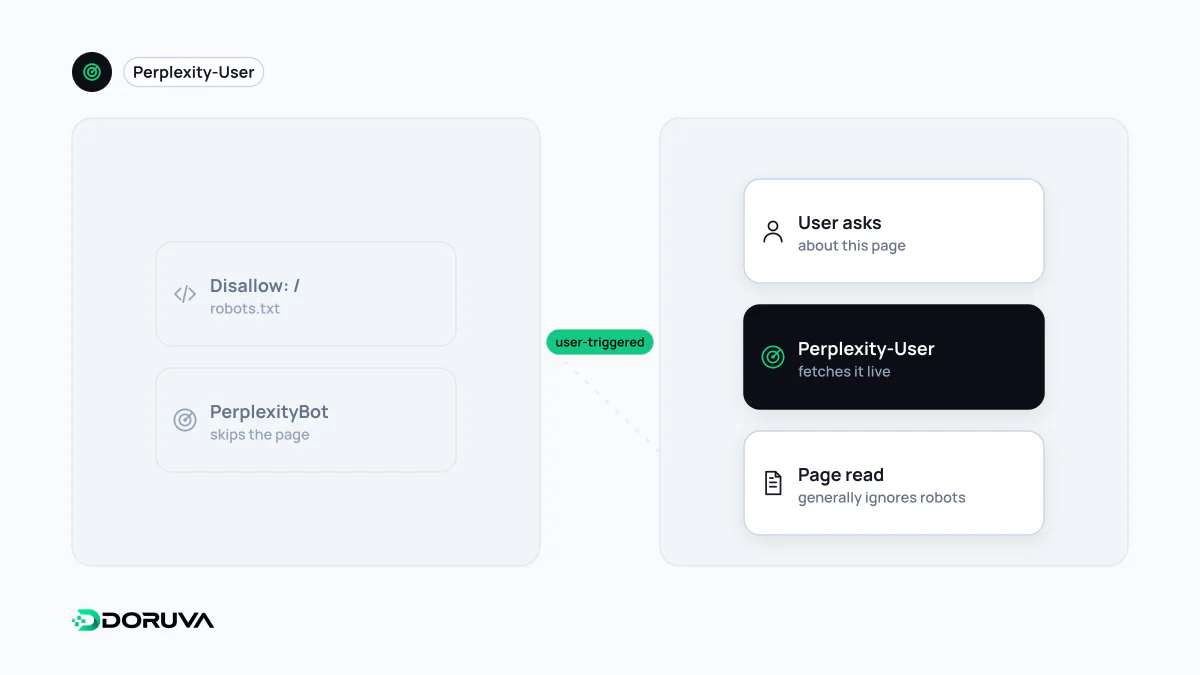
Perplexity-User is the user agent that supports user actions within Perplexity: when someone asks a question, Perplexity may visit a web page to help provide an accurate answer and include a link to that page in its response. Perplexity says it is not used for web crawling or for collecting content to train AI foundation models, and because a user requested the fetch, it generally ignores robots.txt rules.
Also known as: Perplexity User agent, Perplexity-User user agent, Perplexity-User bot, Perplexity user fetcher
A fetcher that links back
According to Perplexity's crawler documentation, Perplexity-User supports user actions within Perplexity. When someone asks a question, Perplexity might visit a web page to help provide an accurate answer and include a link to the page in its response. The same documentation states that this user agent is not used for web crawling or for collecting content to train AI foundation models.
That tells a site owner two things. A visit from Perplexity-User means your page was being read, right then, to build an answer. And when the answer links to you, the visit turns into a chance of referral traffic from people who click through.
Why robots.txt does not stop it
Perplexity says plainly that since a user requested the fetch, this fetcher generally ignores robots.txt rules. By Perplexity's own account, then, the following does not reliably cut off access:
User-agent: Perplexity-User
Disallow: /
That sets it apart from PerplexityBot, which serves Perplexity's search results and for which robots.txt rules do matter. Compared with other providers' user-triggered fetchers, it is also the most explicit statement: OpenAI says rules may not apply to ChatGPT-User, while Anthropic documents that Claude-User can be controlled through robots.txt. Perplexity also notes that changes to its robots.txt tags can take up to 24 hours to be reflected.
Allowing it through a firewall
The more common problem is not blocking Perplexity-User on purpose but blocking it by accident. Perplexity notes that sites using a WAF may need to allow its bots explicitly, and gives configuration steps for Cloudflare and AWS WAF. The full user-agent string it documents is:
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)The recommended rule combines two conditions:
Condition 1: User-Agent contains "Perplexity-User"
AND
Condition 2: Source IP is in one of the ranges listed at
             https://www.perplexity.com/perplexity-user.json
Action:      Allow (with higher priority than blocking rules)
Using both conditions matters: allowing on the user agent alone opens the door to anything that borrows the name. Perplexity says the IP lists are updated regularly and recommends refreshing WAF rules from them automatically.
If you really want it out
Since robots.txt will not do it, the way to stop Perplexity-User is to use the same user-agent and IP match in a blocking rule instead. That choice has a cost: when users ask Perplexity about your page, it cannot be read, and your chances of earning an AI citation in that answer drop. A narrow rule that covers only sensitive directories is usually a better balance than shutting out the whole site.
Before blocking, also confirm that the traffic in your logs really is Perplexity's. Requests that call themselves Perplexity-User but come from outside the published IP ranges belong to some other software; blocking those costs you nothing in Perplexity and deals with the actual source of the load.