

What is ClaudeBot?
Definition
ClaudeBot is Anthropic's web crawler for collecting content that could contribute to training its generative AI models. Disallowing ClaudeBot in robots.txt signals that a site's future content should be excluded from Anthropic's training datasets. Anthropic runs separate bots for other purposes: Claude-User for user-initiated requests and Claude-SearchBot for search quality.
Also known as: Anthropic ClaudeBot, Anthropic crawler, Claude crawler
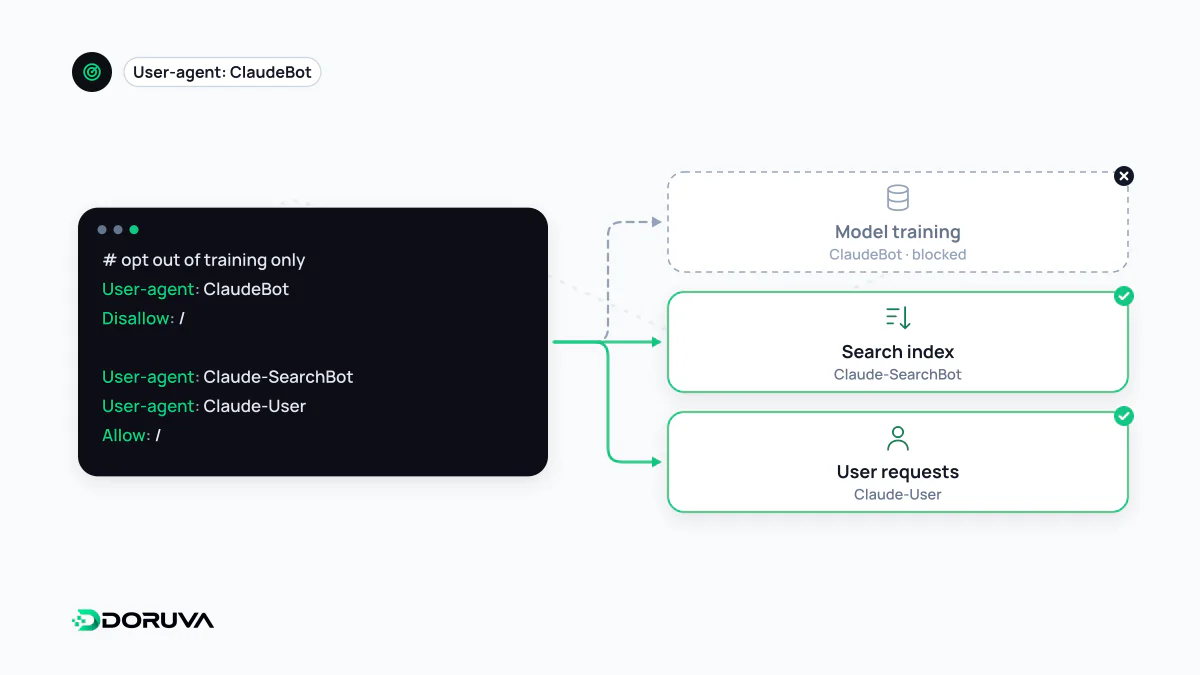
Anthropic's three bots
Anthropic uses three separate bots that access the web for different reasons, and each can be managed independently in robots.txt. The summary below is based on Anthropic's help center article:
| User agent | Purpose | Effect of blocking |
|---|---|---|
ClaudeBot | Collects web content that could contribute to model training | Signals that the site's future content should be excluded from training datasets. |
Claude-User | Retrieves pages when Claude users ask questions | Content cannot be retrieved in response to user queries, which may reduce visibility for user-directed web search. |
Claude-SearchBot | Indexes content to improve search result quality | Content is not indexed for search, which may reduce visibility and accuracy in search results. |
ClaudeBot is the training member of the trio. Whether your site can be used in Claude's web-backed answers depends mainly on Claude-SearchBot and Claude-User. The split mirrors OpenAI's separation between GPTBot and OAI-SearchBot.
Managing it in robots.txt
Anthropic says its bots honor standard "do not crawl" directives in robots.txt. To opt the whole site out of training:
User-agent: ClaudeBot
Disallow: /
To opt out of training while staying available to Claude's search and user requests:
User-agent: ClaudeBot
Disallow: /

User-agent: Claude-SearchBot
User-agent: Claude-User
Allow: /
Anthropic also supports the non-standard Crawl-delay extension. If you want to slow crawling down to reduce server load:
User-agent: ClaudeBot
Crawl-delay: 5
Not every crawler supports this line; Googlebot, for example, ignores Crawl-delay.
Why IP blocking is discouraged
Anthropic warns that blocking its IP addresses may not work correctly or guarantee a lasting opt-out, because it also stops the bots from reading your robots.txt. Stating your preference in robots.txt, where the bot can read it, is how the provider learns what you want.
Watch out for legacy names
Some older guides and robots.txt templates list user agents such as anthropic-ai or Claude-Web. Anthropic's current documentation lists three bots: ClaudeBot, Claude-User and Claude-SearchBot. Keeping the old names does no harm, but relying on them without adding the current ones can leave your intended rule unapplied.
Quick checklist
- Decide on training and search separately; blocking ClaudeBot does not block Claude-SearchBot.
- Remember that once a bot has its own named group, it no longer applies the
User-agent: *rules. - Search your server logs for these names to see which bots actually visit.
For a comparison of bot types across providers, see AI crawler.