

What is Applebot-Extended?
Definition
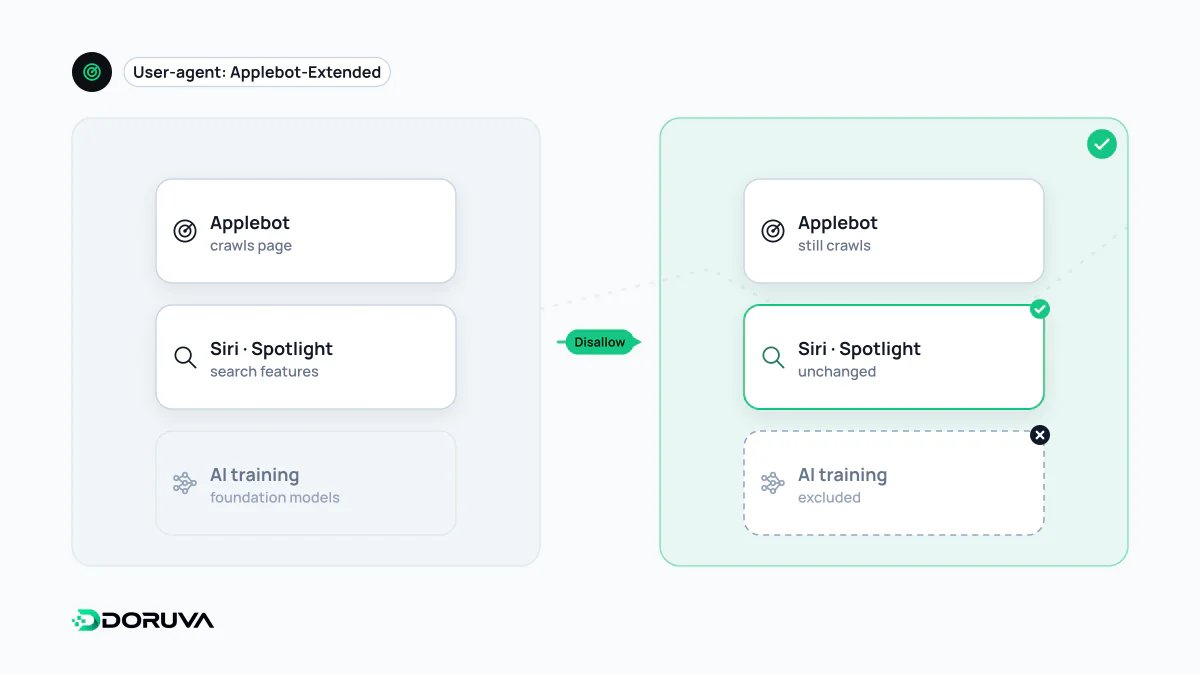
Applebot-Extended is a secondary user agent Apple recognizes in robots.txt that lets web publishers opt out of their content being used to train Apple's general-purpose foundation models, which power generative AI features across Apple products including Apple Intelligence. According to Apple, Applebot-Extended does not crawl web pages; it only determines how data crawled by Applebot may be used, and disallowing it does not remove pages from search results.
Also known as: Applebot Extended, Applebot-Extended user agent, Apple Intelligence training opt-out, Apple AI training opt-out
A usage preference, not a crawler
Apple's crawler on the web is Applebot. According to Apple's Applebot documentation, the data Applebot collects powers search experiences across Apple's ecosystem, such as Spotlight, Siri and Safari. The same data may also be used to help train the foundation models behind generative AI features across Apple products, including Apple Intelligence, Services and Developer Tools. Applebot-Extended is how a publisher opts out of that second use.
Apple states explicitly that Applebot-Extended does not crawl web pages and is used only to determine how to use the data crawled by Applebot. You will therefore never see a request under that name in your server logs. The design resembles Google's Google-Extended token: neither is a separate bot, both are a preference about what an existing crawler's data may be used for.
Three controls, three outcomes
Apple's documentation describes three controls related to AI use that are easy to mix up:
| Control | What it changes | What it leaves alone |
|---|---|---|
Disallow for Applebot-Extended | Whether content is used to train Apple's general-purpose foundation models | Crawling and inclusion in search results; Apple says rules for Applebot-Extended are not considered in Search ranking |
nosnippet meta tag | Whether content is used as additional context when AI models generate output in Apple products (for example broad world-knowledge answers in Siri and Search); no description or web answer is generated for the page | Crawling and indexing of the page |
Disallow for Applebot | Crawling itself, so the content cannot appear in Apple's search features | Other providers' bots |
The crucial point is that Applebot-Extended is about training, not about answer generation. If you do not want content used as context in AI-assisted answers in Siri or Search, the tool Apple points to is the nosnippet directive. Apple also says pages marked isAccessibleForFree: false in structured data remain eligible for search results but will not be used as additional context for AI-generated output.
robots.txt examples
Keep the whole site out of Apple's foundation model training:
User-agent: Applebot-Extended
Disallow: /
Exclude a single directory (the example in Apple's documentation):
User-agent: Applebot-Extended
Disallow: /private/
Neither rule stops Applebot from crawling. Apple says that as long as Applebot is allowed, content stays discoverable through Spotlight, Siri and Safari. To weigh this alongside other providers' training preferences, see GPTBot and AI crawler.
Two Applebot quirks worth knowing
- It falls back to Googlebot rules. Apple says that if robots.txt does not mention Applebot but does mention Googlebot, Applebot follows the Googlebot instructions. Googlebot-specific restrictions can therefore affect Apple's crawling too.
- No Crawl-delay. Apple says Applebot does not follow
Crawl-delay; instead it adjusts its crawl rate automatically when a site slows down or returns errors.
Genuine Applebot traffic can be verified with a reverse DNS lookup that resolves into the *.applebot.apple.com domain, or by matching the IP address against Apple's published list at https://search.developer.apple.com/applebot.json.