

What is Relevance Scoring?
Definition
Relevance scoring is how a search system expresses, as a number, how relevant a document or passage is to a particular query; results are then sorted by that number. Classic methods rely on word statistics such as TF-IDF and BM25, while modern methods use embedding similarity and cross-encoder models. Large search engines combine these scores with many other signals.
Also known as: relevance score, BM25, TF-IDF, Okapi BM25, lexical scoring
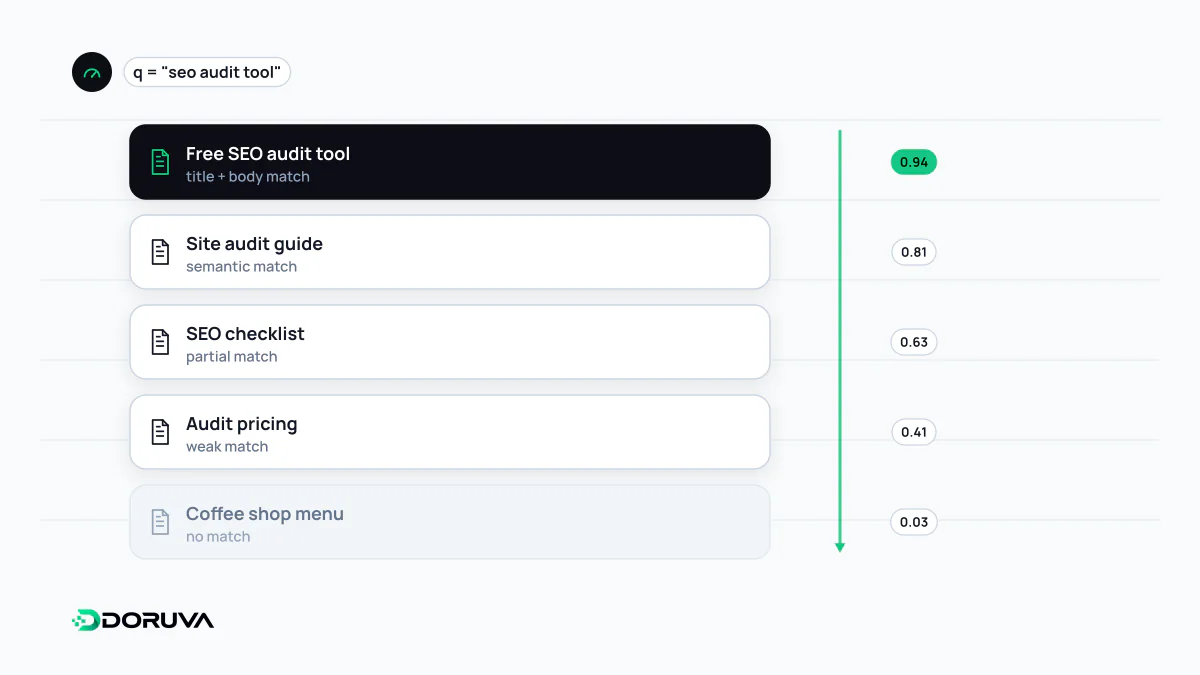
What a relevance score does and does not measure
A relevance score answers one narrow question: how closely does this text match this query? It is not a measure of quality, trustworthiness or freshness; those are separate signals. Scores are also relative. Comparing a document that scored 12.4 for one query with another that scored 8.1 for a different query tells you nothing; what matters is how candidates rank against each other for the same query. Large search engines never use relevance on its own. Google's guide to its ranking systems lists systems for understanding language and intent alongside others focused on reliable information, original content and freshness.
TF-IDF: frequency times rarity
The classic starting point for lexical relevance is TF-IDF, built from two parts:
- TF (term frequency): how many times a query word appears in the document. Frequent use suggests the document is about that topic.
- IDF (inverse document frequency): how rare the word is across the collection, commonly log(N / df), where N is the number of documents and df the number containing the word.
In a collection of 10,000 documents, a word like "the" that appears in all of them has an IDF of ln(10,000 / 10,000) = 0; it separates nothing. A word like "canonical" that appears in only 50 has an IDF of ln(200) ≈ 5.3, so matching it adds a lot. For the query "canonical URL and the redirect chain", the rare words do the real work.
BM25: putting a ceiling on repetition
TF-IDF's weakness is that term frequency counts without limit: a document repeating a word 50 times looks ten times more "relevant" than one using it 5 times. BM25 fixes this with two parameters. Its common form is:
score(D, Q) = Σ IDF(q) · [ f(q,D) · (k1 + 1) ] / [ f(q,D) + k1 · (1 − b + b · |D| / avg_len) ]Here f(q, D) is how often query term q occurs in document D, |D| is the document's length and avg_len the average length in the collection. k1 controls how quickly term frequency saturates, and b how strongly scores are normalized for length. Elasticsearch uses BM25 as its default similarity, with defaults of k1 = 1.2 and b = 0.75.
With those values, for a document of average length, the frequency component behaves like this:
| Occurrences of the term | Frequency component |
|---|---|
| 1 | 1.00 |
| 3 | 1.57 |
| 10 | 1.96 |
| Very many | Approaches 2.20 (k1 + 1) |
Using a word ten times does not even double the contribution of using it once. Length normalization pushes the same way: in a document twice the average length, a single match contributes about 0.71 instead of 1.00. That is the arithmetic behind why keyword stuffing yields diminishing returns even in the simplest lexical models.
Semantic scores
Word matching misses text that says the same thing in different words. Methods that close that gap produce scores in other ways:
- Embedding similarity. Query and document are turned into embeddings, and the score is a measure such as the cosine similarity between the two vectors.
- Cross-encoder scores. Query and passage go into a model together and it outputs a relevance score directly. More accurate but more expensive, so it is usually reserved for reranking.
- LLM judgments. A language model is asked to rate how well a passage answers the question.
These scores live on different scales: BM25 has no upper bound, while cosine similarity sits in a narrow range. Ways of merging result lists from different methods are covered under hybrid search.
Lessons for SEO and GEO
Two plain lessons follow for content. First, repeating a word stops paying off quickly; covering the terms, entities and sub-questions a topic actually involves does far more. Second, semantic scoring rewards text that serves the search intent behind a query, so a paragraph that contains the right words but never answers the question tends to lose out at stages such as reranking. No scoring method guarantees a ranking on its own. High relevance is one prerequisite for visibility among several; for how it sits alongside other signals, see ranking factor.